Overfitting: When Your AI Learns Too Well… and Misses the Essentials
Discover how overfitting prevents AI models from generalizing well and simple techniques to avoid it.
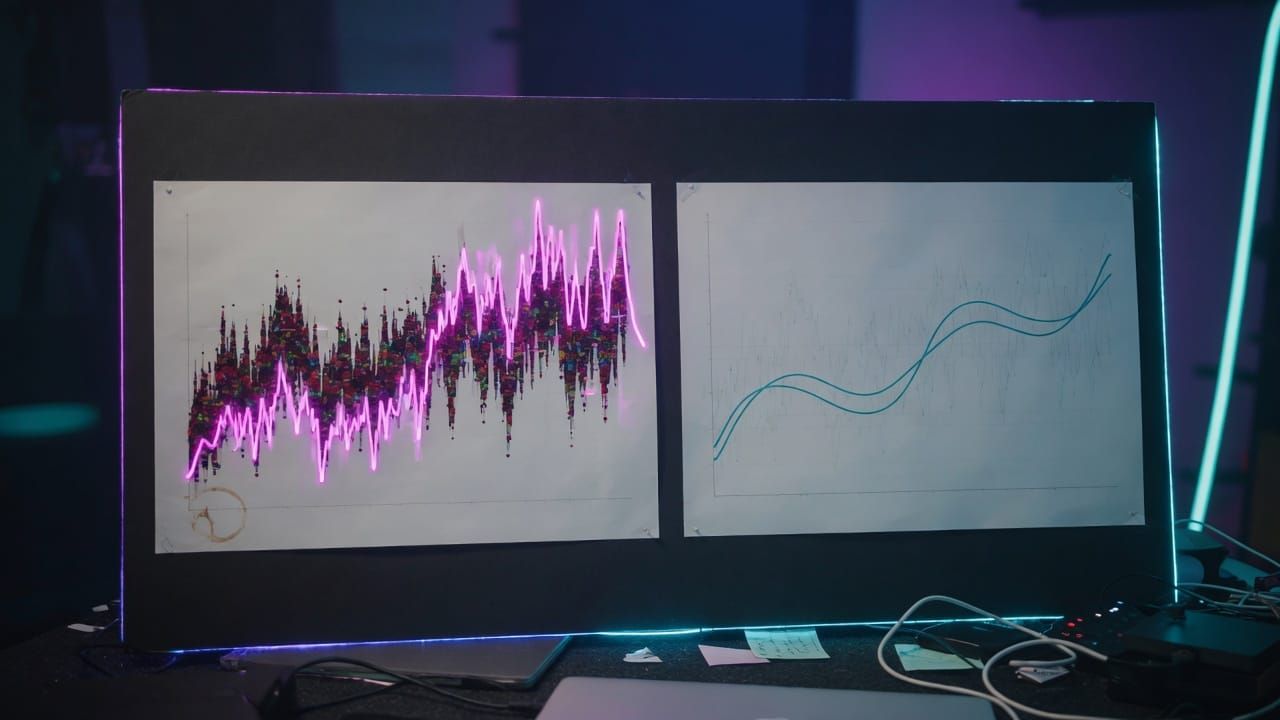
Imagine a student who memorizes by heart all the answers in a textbook without understanding the concepts: they will perfectly succeed on the exercises already seen, but will fail when faced with a new question. This is exactly what happens with overfitting in artificial intelligence. This phenomenon, also called overfitting, is one of the most common pitfalls when training a model. It is therefore essential to understand it in order to build truly high-performing systems.
What is overfitting?
Overfitting occurs when a model learns not only the general patterns in the training data, but also the noise and specific details unique to that dataset. As a result, it achieves excellent performance on the training data but poor performance on unseen data. Generalization—that is, the ability to perform well on new data—suffers directly.
Why does this happen?
Several factors favor overfitting:
- The model is too complex relative to the amount of data (too many parameters).
- The training data contains noise or anomalies.
- The training lasts too long without control.
- The dataset is too small or not diverse enough.
These situations push the model to “memorize” rather than to “understand”.
How to Spot Overfitting?
The clearest sign is a large gap between performance on the training set and performance on the validation or test set. If training accuracy reaches 98% while validation accuracy plateaus at 75%, it is highly likely that the model is overfitting. Learning curves can also help visualize this phenomenon: the training curve continues to decrease while the validation curve rises or plateaus.
How to combat overfitting?
Fortunately, several effective techniques exist:
- Increase the quantity and diversity of the data.
- Simplify the model (reduce the number of layers or neurons).
- Use regularization (L1, L2) which penalizes overly large weights.
- Apply dropout in neural networks.
- Stop training as soon as validation performance stops improving (early stopping).
- Use cross-validation to better evaluate the model’s robustness.
A Simple Example in Python
Here is an excerpt illustrating the use of cross-validation and early stopping with scikit-learn:
from sklearn.model_selection import cross_val_score
from sklearn.ensemble import RandomForestClassifier
model = RandomForestClassifier(n_estimators=100)
scores = cross_val_score(model, X, y, cv=5)
print("Score moyen :", scores.mean())
This approach makes it possible to obtain a more reliable estimate of the model's actual performance on unknown data.
By mastering overfitting, you will build AI models capable of adapting to new situations rather than simply repeating what they have already seen. This is the key to truly useful and reliable artificial intelligence in the real world.
💬 Have a question or want to go further? Join the community on Discord: https://discord.gg/GwhUKccQcM