Gradient Descent Explained Simply: The Engine of Machine Learning
Understand how this algorithm optimizes AI models by minimizing errors, with concrete examples for beginners.
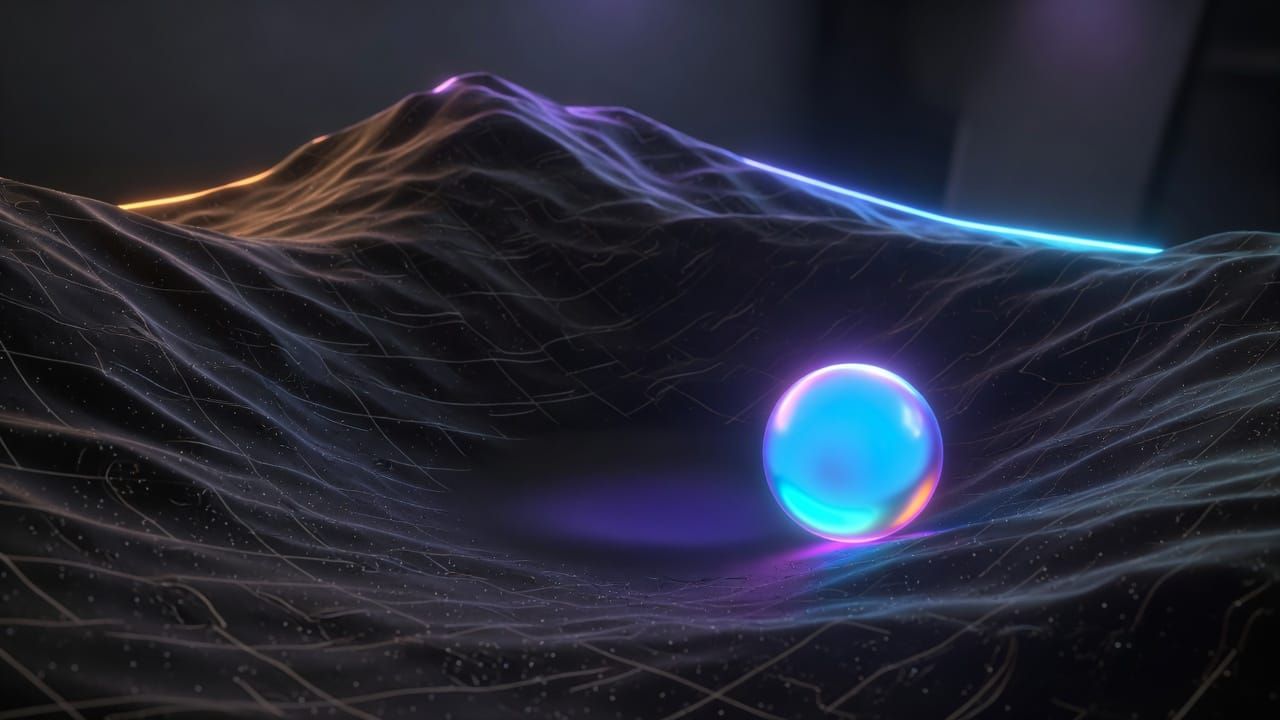
Imagine you're lost in a misty valley and searching for the lowest point to find your bearings. Each step you take depends on the slope beneath your feet: you descend where the slope is steepest. This is exactly what gradient descent does in artificial intelligence: an algorithm that guides a model toward the best solution by gradually adjusting its parameters.
The Intuitive Principle Behind Gradient Descent
In machine learning, a model learns by minimizing a cost function that measures the discrepancy between its predictions and reality. Gradient descent computes the slope of this function at each point and updates the parameters in the direction opposite the slope. The steeper the slope, the larger the adjustments at the start. Gradually, the model slows down near the minimum, like a hiker braking upon reaching the valley floor.
- The cost function represents the model’s overall error.
- The gradient indicates the direction and intensity of the slope.
- The learning rate controls the size of the steps taken.
A Concrete Example with Linear Regression
Suppose we want to predict the price of an apartment based on its surface area. We start with random parameters for the regression line. At each iteration, gradient descent calculates the average error over all the data and adjusts the slope and the y-intercept. After a few hundred iterations, the line gradually aligns with the real points in the dataset.
theta = theta - learning_rate * gradientThe most commonly used variants
The classic version, called batch gradient descent, uses all the data at each step. It is precise but slow on large volumes. Stochastic gradient descent (SGD) updates the parameters after each example, which speeds up learning but makes the trajectory noisier. Between the two, mini-batch combines the advantages of both approaches and now dominates modern frameworks like TensorFlow or PyTorch.
- Batch: full computation, stable but expensive convergence.
- SGD: fast updates, risk of oscillations.
- Mini-batch: ideal compromise for most cases.
Concrete Applications in AI
Gradient descent lies at the core of neural networks, computer vision, and natural language processing. When an image recognition model learns to distinguish a cat from a dog, it adjusts millions of weights using this method. Without it, training models like GPT or Stable Diffusion at scale would be impossible.
Common Pitfalls and How to Avoid Them
A learning rate that is too high causes the model to oscillate without converging, while one that is too low slows learning down dramatically. Local minima can also trap the algorithm in suboptimal solutions. Techniques such as momentum or adaptive learning rate adjustment (Adam) help overcome these challenges.
Gradient descent remains the fundamental tool that allows AI to learn from data. By understanding how it works, you lay the foundations for exploring more advanced algorithms and designing your own models with confidence.
💬 Have a question or want to go further? Join the community on Discord: https://discord.gg/GwhUKccQcM