Handling Imbalanced Datasets: Techniques and Best Practices
Understanding imbalanced datasets and mastering methods to train reliable models in classification.
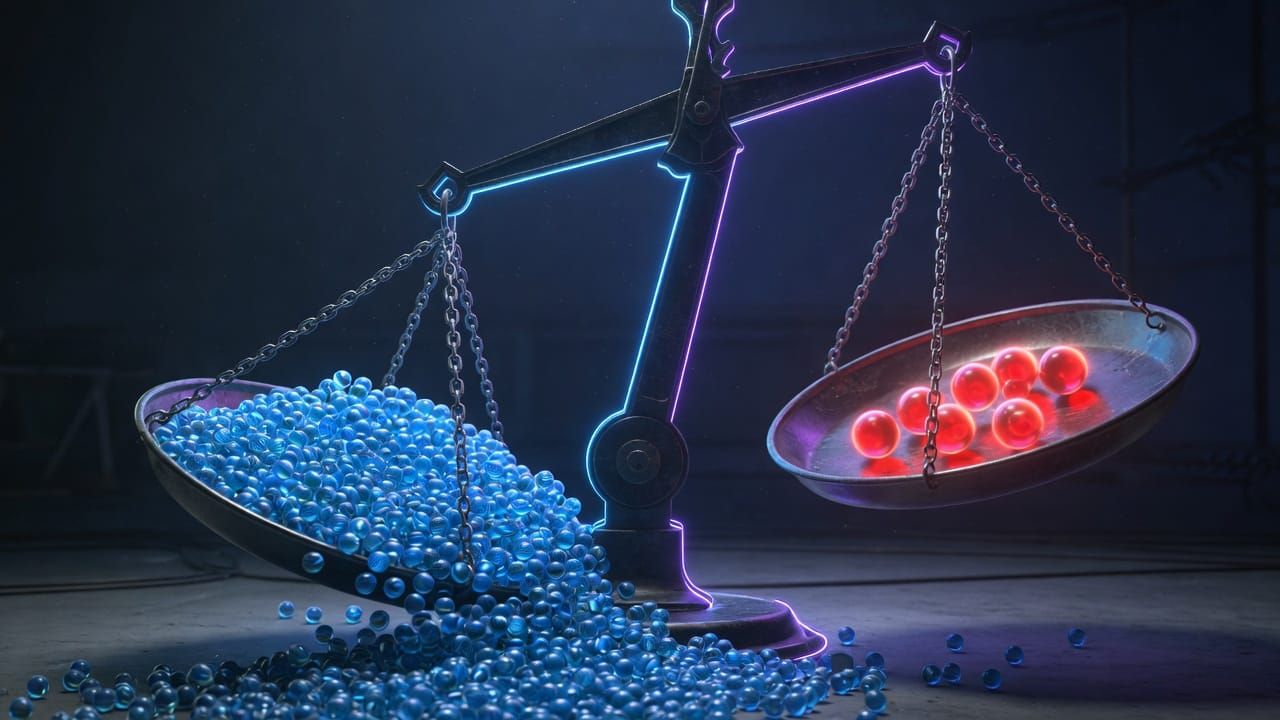
Imbalanced datasets pose a major challenge in machine learning. When one class accounts for 99% of the examples and the other only 1%, traditional algorithms tend to “cheat” by always predicting the majority class. This article walks you through identifying, measuring, and correcting this issue with proven techniques.
1. What is an imbalanced dataset and why is it a problem?
A dataset is imbalanced when the class distribution is very unequal. Concrete examples abound: bank fraud detection (0.1% of fraudulent transactions), medical diagnosis of rare diseases, customer churn prediction, spam filtering or industrial defect detection. In all these cases, the model that systematically predicts the majority class achieves high accuracy while being totally useless.
2. The Accuracy Trap and Appropriate Metrics
Accuracy is misleading because it masks errors on the minority class. One should prioritize the confusion matrix, precision, recall, the F1 score, balanced accuracy, Cohen’s Kappa, and especially PR-AUC (more relevant than ROC-AUC when classes are highly imbalanced). Recall is prioritized when false negatives are costly (missed disease) and precision when false positives are (unnecessary fraud alert).
3. Resampling Techniques
Oversampling duplicates or synthesizes minority examples (SMOTE, ADASYN, Borderline-SMOTE). Undersampling removes majority examples (Random, Tomek links, NearMiss, ENN). Combinations such as SMOTETomek or SMOTEENN often provide the best compromise. Caution: oversampling can cause overfitting and undersampling a loss of valuable information.
4. Algorithm-Level Approaches
Algorithms can directly incorporate imbalance via the class_weight parameters or cost-sensitive learning. Adjusting the decision threshold (threshold moving) makes it possible to optimize recall or precision according to business needs. Focal Loss, used in deep learning, reduces the impact of easy examples and focuses learning on difficult cases.
5. Specialized Ensemble Methods
Adapted ensemble methods include BalancedRandomForest, EasyEnsemble, RUSBoost and BalancedBagging. They combine resampling and model aggregation to improve robustness while limiting overfitting.
6. Switching to Anomaly Detection Mode
When the rare class represents less than 1% of the data, it becomes relevant to switch to anomaly detection approaches (Isolation Forest, One-Class SVM, autoencoders). These methods model only the majority class and flag points that deviate strongly from it.
7. Validation Best Practices
Resampling should never be applied to the test or validation set. Always use a pipeline (imblearn.Pipeline) and stratified k-fold cross-validation. This avoids any data leakage and ensures an honest evaluation of performance.
8. Concrete Example with Python and imbalanced-learn
from sklearn.datasets import make_classification
from sklearn.model_selection import train_test_split, StratifiedKFold
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import classification_report
from imblearn.pipeline import Pipeline
from imblearn.over_sampling import SMOTE
from imblearn.under_sampling import RandomUnderSampler

X, y = make_classification(n_classes=2, weights=[0.95, 0.05],
                           n_informative=4, flip_y=0, n_samples=5000,
                           random_state=42)
X_train, X_test, y_train, y_test = train_test_split(X, y, stratify=y,
                                                    test_size=0.2, random_state=42)

pipeline = Pipeline([
    ('over', SMOTE(random_state=42)),
    ('under', RandomUnderSampler(random_state=42)),
    ('clf', RandomForestClassifier(class_weight='balanced', random_state=42))
])

pipeline.fit(X_train, y_train)
y_pred = pipeline.predict(X_test)
print(classification_report(y_test, y_pred))
Conclusion: when faced with an imbalanced dataset, always start by analyzing the class distribution and choosing the right metrics. Then test resampling techniques, weighting, and ensemble methods in a rigorous pipeline. Here is a practical checklist so you don’t forget anything:
- Analyze the class distribution from the start
- Use stratified k-fold and imblearn pipelines
- Prioritize recall, F1 and PR-AUC over accuracy
- Try SMOTE then adjust the decision threshold
- Compare class_weight and ensemble methods
- Switch to anomaly detection if the minority < 1 %
- Validate only on non-resampled data
💬 A question or want to go further? Join the community on Discord : https://discord.gg/GwhUKccQcM