Classification vs Regression: Mastering the Two Key Approaches in Supervised Learning
Learn to distinguish classification and regression in AI thanks to concrete examples and practical advice for choosing your model well.
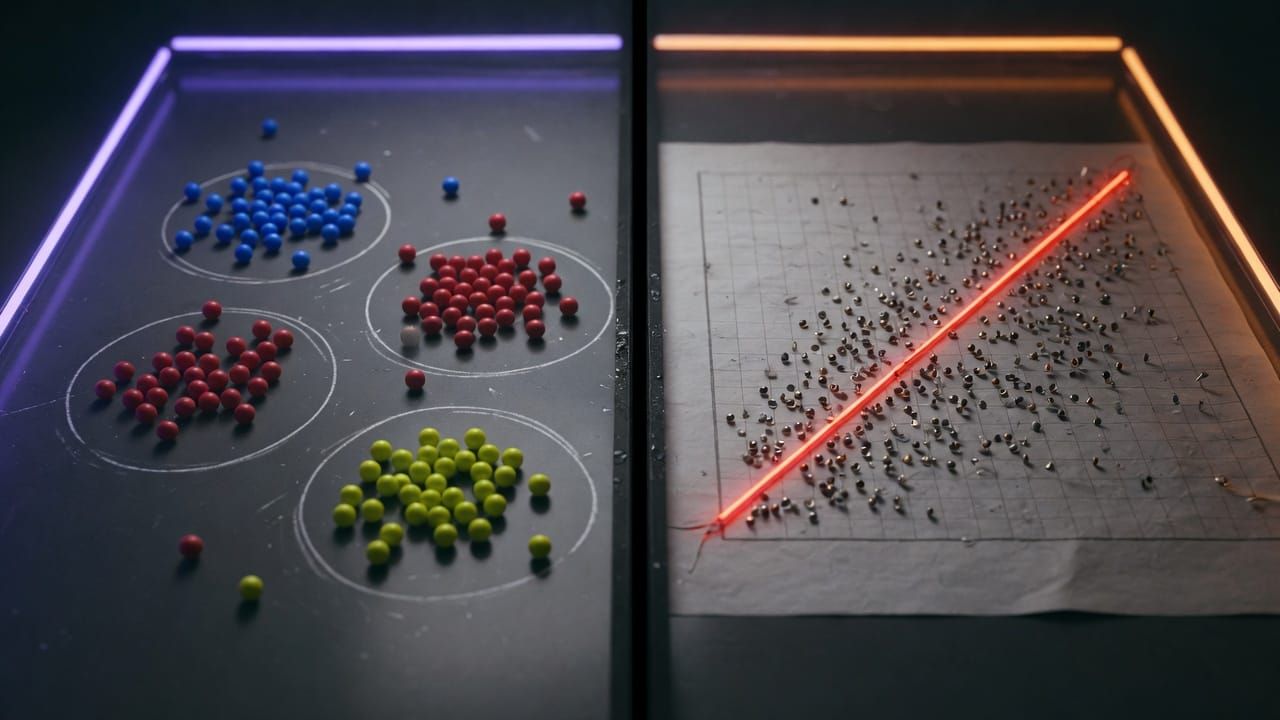
In the world of artificial intelligence, supervised learning is one of the most widely used techniques. Two methods dominate this field: classification and regression. Understanding their differences enables us to effectively solve many real-world problems, from medical diagnosis to sales forecasting.
What is supervised learning?
Supervised learning involves training a model from labeled data. You provide the system with examples that have known inputs and outputs so it learns to predict the output for new data. It's like teaching a child to recognize fruits by showing them already identified apples and bananas. This approach is mainly divided into two categories based on the nature of the expected output.
Regression: Predicting Continuous Values
Regression aims to predict a continuous numerical value. For example, estimating the price of a house based on its size, location, and number of bedrooms. The model learns to draw a line or curve that minimizes the difference between its predictions and the actual values. Common algorithms include linear regression or random forests for more complex relationships. The goal is to minimize the error on values that can be any real number.
Classification: Assigning Categories
Classification assigns a discrete label or a category. Think of detecting whether an email is spam or not, or identifying a flower species from petal measurements. The model learns to separate the data into distinct classes. Logistic regression, decision trees, or neural networks are often used. The output is generally a probability or a precise class, such as “spam” or “not spam”.
Key Differences Between the Two Approaches
The primary distinction lies in the nature of the target variable: continuous for regression, discrete for classification. In regression, error is measured as numerical distance (e.g., price deviation), while in classification we assess the rate of correct predictions or the confusion matrix. Metrics also differ: RMSE for regression, precision or recall for classification. Finally, classification problems often deal with class imbalances, unlike regression.
Concrete Examples and Algorithm Choices
Let's imagine a weather forecasting project: regression to estimate the exact temperature tomorrow, classification to say whether it will rain or not. Another case: predicting a client's future revenue (regression) versus determining whether they will cancel their subscription (classification). Here is a simple example in Python with scikit-learn:
from sklearn.linear_model import LinearRegression, LogisticRegression
# Regression: predict a price
model_reg = LinearRegression()
# Classification: predict a class
model_clf = LogisticRegression()
How to Choose Between Classification and Regression?
First, observe your target variable: is it a continuous number or a category? Then test the data distribution and the business question. If you want a precise value like an amount, opt for regression. For binary or multiclass decisions, classification is suitable. Feel free to transform a problem (for example, grouping ages into brackets) to switch from one approach to the other according to your needs.
In conclusion, classification and regression are complementary and cover the majority of use cases in supervised learning. Mastering their differences will help you design more relevant and performant AI solutions from your first projects.
💬 Have a question or want to go further? Join the community on Discord: https://discord.gg/GwhUKccQcM